


Using a Raspberry Pi Pico RP2040 and the Edge Impulse Platform
Machine learning and voice-controlled applications such as Alexa and Siri are major features of modern technology. In this article, two Cornell University students describe a game they designed and built, to see how well their machine-learning system on a low-power MCU could correctly classify the names of colors spoken by users.
Artificial intelligence (AI) and machine learning (ML) are becoming increasingly prevalent and popular today, with the modern addition of ChatGPT and other AI-based chatbots. We already interact with these technologies in our daily life. Most voice-controlled devices use machine learning to detect speech patterns and correctly identify commands and requests. Due to the increasing popularity of AI and ML, we decided to design and build a machine learning, voice-controlled game that demonstrates the “Stroop effect.” The Stroop effect is the delay in reaction time between congruent and incongruent stimuli. Players need to correctly say the name of the color displayed in text rather than the color of the text displayed to them.
We decided to build a keyword-spotting system much like Alexa or Siri. Keyword spotting refers to the detection of words or phrases used in phone calls or audio recordings, or finding all occurrences of a query word that exist in a scanned document image. Given that keyword-spotting technology is already being used extensively to make online searches and inquiries with smartphones and smart assistant devices easier and more efficient, we were curious to see if we could run and deploy an ML model on a low-power microcontroller, the Raspberry Pi Pico RP2040.
Voice-controlled applications are part of the future of modern technology, so this project was a good introduction to the world of machine learning and voice-powered projects. Completing this project opens the door for future projects to be more complex and challenging, based on the architecture we created.
To build such a system, we acquired over 800 audio samples, extracted the MFCC (Mel-frequency cepstral coefficients) features from the audio samples, designed and trained a neural network (NN) model using the open-source Edge Impulse development platform [1], designed the breadboard circuitry—using a electret microphone along with some LEDs—and used the deployed model on the RP2040 to make a fun and challenging reaction game.
This project was part of the ECE 4760 Microcontrollers class at Cornell University. Under the guidance of Professor Hunter Adams, we were given 4 weeks to design and implement a project of our choosing.
HIGH-LEVEL DESIGN
Our curiosity and research about deploying a complex ML model on low-power microcontrollers led us to the little-known field of “tinyML.” We gathered project ideas and implementation tips from Gian Marco Iodice’s TinyML Cookbook [2] Tiny ML is the field where machine learning and embedded systems intersect to make AI possible with low-powered microcontrollers and other devices.
The hardware schematic (Figure 1) shows the general design of our circuit. Connected to the Raspberry Pi Pico are a microphone, a headphone jack (for analog audio input), a button to control when the device starts listening, and a series of LEDs. The LEDs and the headphone jack were used for testing purposes. In early versions of the system, in which we didn’t have VGA output, we used the LEDs to show a correct response. In trying to troubleshoot the microphone, we connected the headphone jack to provide audio samples identical to those used to train the ML model to the Raspberry Pi. All the audio processing and ML computation is done on the Raspberry Pi Pico which is connected to all these peripherals.

Hardware schematic.
Acquiring Audio Data: To get proper voice classification, several steps need to occur. First, audio data is collected through the microphone. Then, this audio data is processed, and the waveform is transformed into a useable spectrum for machine learning classification. In the ML model, the algorithm matches patterns in the processed waveform to patterns in the sample data on which it was trained. For our project, we created red, green, blue, yellow, magenta, cyan, and white classes that the model would correctly match against.
To collect the audio samples for training and testing the ML model, we used our smartphones and connected to a free Edge Impulse account. We then began recording the sound signals for the seven different color classes. We collected roughly 130 audio samples for each of the colors red, blue, green, yellow, magenta, cyan, and white, and 100 audio samples for the “unknown” class, which was designed to match against if the model could not correctly classify the color as one of the seven.
The raw audio waveform is a filtered signal the smartphone sends over to the Edge Impulse platform. The signal represents a quantity that varies over time. Sound signal for example is a variation in air pressure. It represents variations in air pressure over time. Since the microphone is a measurement device, it measures these variations and generates an electrical signal that represents sound. A single audio waveform of “yellow” is shown in Figure 2. The microphone, much like a speaker, is also known as a transducer, because it converts our speech signals from one form to another. This raw data is collected and sent through multiple processing stages, to reach a result that we used to classify the data.
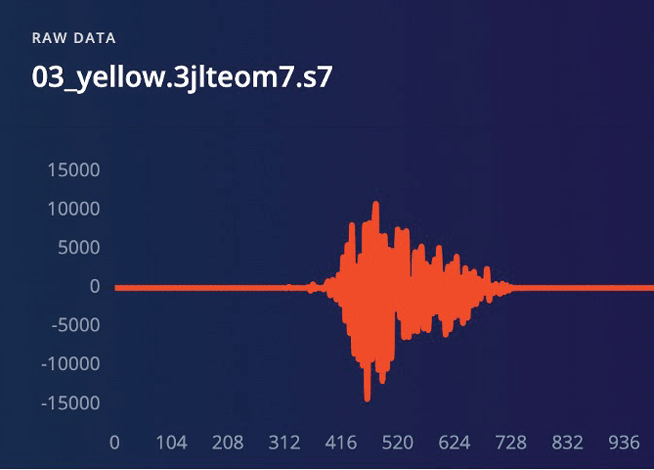
Single audio waveform of “yellow.”
Once the audio signals were converted and sent over to the Edge Impulse platform, we examined the MFCC features used to distinguish the colors from each other, so that the model could accurately classify them.
MFCCs are a way to break down audio signals into raw data that can be analyzed to find specific features. For example, the MFCC’s of a person saying “red” is different from the MFCCs of a person saying “green,” so by comparing the different MFCCs, one can distinguish between the two colors. A multi-word waveform split into distinct words is shown in Figure 3.
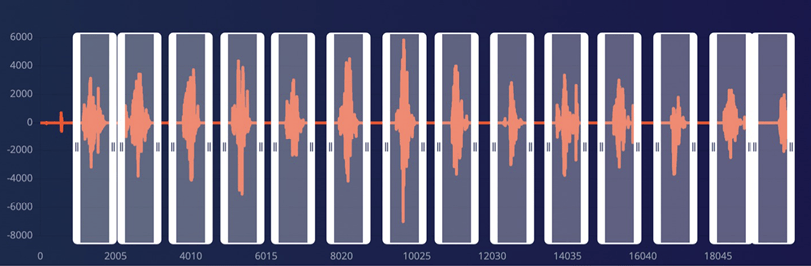
Multi-word waveform being split into distinct words.
Also on Edge Impulse, the signals are passed through two main computational blocks: the “processing block,” which prepares the samples for the ML algorithm; and the “learning block,” which is where the model learns the features of the data samples.
In the processing block, a Discrete Fourier Transform (DFT) is performed on the audio signals to obtain the spectrograms of the waveforms. This can be thought of as an audio signal’s image representation. However, for audio speech signals in particular, we not only need to obtain the spectrograms, but also need to adjust them, so that the frequencies are on levels of what humans can perceive.
The loudness is also adjusted to scale logarithmically rather than linearly as follows:
- Scaling the frequency to Mel with the Mel-scale filter bank: The Mel scale is commonly computed using triangular filters overlapped in frequency domain. The Mel scale remaps the frequencies, so that they are distinguishable. For instance, with such a filter, if we were to play pure tones from 100Hz to 200Hz with a 1Hz step, we could hear each frequency step. But if such a filter were used at higher frequencies of 7,500Hz and 7,600Hz, we would barely be able to hear the tones, because such frequencies are simply too high to be perceived by the human ear. Human ears are less sensitive to these small variations at high frequencies.
- Scaling the amplitudes using the decibel (dB) scale: The human brain does not register sound amplitude linearly, but rather, logarithmically. Therefore, we need to scale the amplitudes of audio signals logarithmically, as shown in Figure 4.
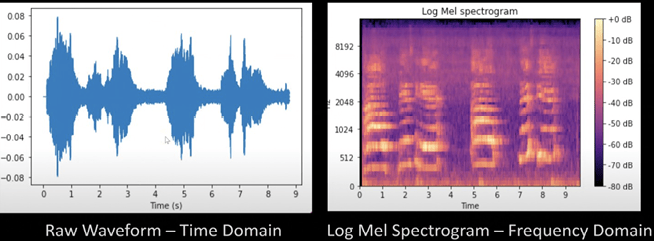
Mel spectrogram example.
Extracting MFCC: From the output of the Mel filter, we can still cut down on the number of component features, while retaining the distinctive features that the model can use to do accurate classification. MFCC aims to extract fewer and highly unrelated coefficients from the Mel spectrogram. The Mel filter bank uses overlapping filters, which makes the components highly correlated. We can decorrelate the output by applying a Discrete Cosine Transform (DCT). The resulting spectrogram has fewer frequencies than the Mel spectrogram.
From the feature explorer, we can infer whether the input features are distinct and suitable for our problem, by seeing the classes (except the “unknown” category) well separated and classified on the 3D scatter plot. As shown in the plot (Figure 5), the model does a fairly good job of separating the different colors. The dots in the middle of the plot show words that are similar sounding to each other, so there is less distinction between the resulting data with those words. The off-colored dots represent inaccuracies, where the model failed to correctly classify the words.

Scatter plot showing classification of colors.
Now that we have successfully extracted the minimal number of features that the model can use to train and test, we can proceed to designing and training the neural network (NN) model.
The NN model (Figure 6) has two, 2-dimensional (2D) convolution layers, one dropout layer and a fully connected layer. The network’s input is the MFCC feature extracted from the 1s audio samples into which we split the audio data.

Block diagram of Neural Network processing.
SOFTWARE DESIGN
A complete version of our code is available on the Circuit Cellar Article Materials and Resources webpage [3]. Our code consists largely of multiple functions to record from the microphone, classify the audio input based on our ML model, and code to update the VGA display based on what color name the user spoke. We tried to make our program multi-threaded (by off-loading the VGA updating to another core), but this introduced problems with the recording of the audio data and the classification of the audio against our ML model, so we ultimately decided against it.
When starting up the Raspberry Pi Pico, nothing visually happens. The int main() function runs, and it correctly initializes all the GPIO pins we use, sets up the ADC (Analog-to-Digital Converter), and initializes the array used to store the raw ADC data. Then, the main thread is scheduled, and a basic while loop executes. Before reaching the infinite while loop, the program resets a variable to zero. This keeps track of how many colors the user got correct consecutively.
If the physical button on the board is not pressed, nothing happens, and the program keeps cycling through the loop. When the user presses the external button on the board, however, the program enters the loop, the VGA display is initialized, and the color and word variables are randomized, based on how long it has been since the program started executing. This ensures a new random color every time the button is pressed (unless, of course, the user gets exactly the same timing on each run, down to the millisecond).
After this, a color is spelled out in text on the display, in a different font color than the word name (for example, the word “red” is displayed in blue). The program sleeps for 700ms to give the user a small window to process the information on the screen. Next, the timer record function is run. This function essentially sets up a repeating timer to go off for a desired sampling period.
Inside the timer ISR (Interrupt Service Routine), the sample buffer is filled with audio samples from the ADC. One thing that was tricky here was taking out the bias from microphone amplification. To do this, we had to determine the bias of the amplifier which is VCC/2 and subtract it from each ADC value.
Once the buffer is full, the repeating timer is cancelled, and the program returns to the main thread loop. The microphone buffer is then sent through our machine learning model. All the machine learning classification is done with a library from Edge Impulse, which was created based on the model we created using their online platform. The cool thing about Edge Impulse is that the model we created online using voice samples can be outputted as a C++ library. This means that all the machine learning processing can be done on a local machine instead of the Cloud [4]. (This will be discussed later in the RESULTS section.) The run_classifier function from Edge Impulse takes in a signal_t type with raw sensor data and returns the result in a custom ei_impulse_result_t type. The latter contains data such as the classification, the time it took to compute the classification, and any anomalies that occurred when doing the classification.
After getting the results, the different color categories are compared against a set classification percentage (in our case, 60%), and it is also compared against the color displayed on the VGA screen. The VGA screen is then updated. If the user names the color correctly, the streak variable is incremented, and a correct message is displayed on the VGA screen. There are also results displayed if the classification fails and if the user gets it wrong.
After displaying the results to the user, the loop starts again, and waits for the user to press the button to try the game again. If the user gets answers correctly, the streak variable persists through each game play. If the user gets it wrong or the classification fails, the streak variable is reset to zero before the loop starts again.
HARDWARE DESIGN
For the most part, our circuit design was simple. The circuitry consisted of wiring for the VGA display, the microphone, three LEDs we used for testing the ML model, and the headphone jack circuit with voltage divider.
The VGA display, microphone output, and button were connected to different GPIO pins on the Raspberry Pi Pico. In the code, these GPIO pins are manipulated to produce the desired output or receive the proper input. For example, when correctly classifying a color, the corresponding LED’s GPIO pin is sent a “1” signal to turn on the LED.
Besides the voltage divider circuit, the wiring for this project was pretty simple. We wired up a headphone jack and voltage divider for testing purposes. The voltage divider circuit served to take the output from the headphone jack, and send a useable signal to the Pico. The headphone jack from a computer outputs non-standard voltage that the Pi cannot use, so the divider circuit is meant to scale the voltage so the Pi can read the output. The headphone jack outputs around ±3V, and the RP 2040 ADC can read from 0-3.3V, so the divider circuit is necessary to give the Pi data it can read. A schematic of the voltage divider circuit is shown in Figure 7.
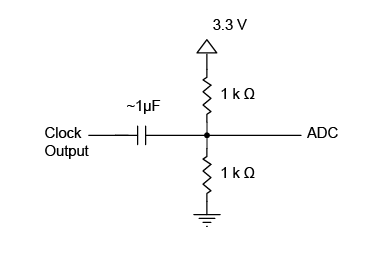
Voltage divider circuit.
Design Problems: While creating and testing the ML model on the Raspberry Pi, we ran into some complications that made it difficult to complete. Our first issue arose with the classification of the audio. It seemed in the early stages that the model would only recognize certain people’s voices. We suspected this was likely due to the model not being trained enough. After going back and retraining the model with more sample data, we found that the classification did not improve much. We were still getting erroneous results. The consistency of our model was spotty at best. Some days it would work perfectly, and other days it would not work at all.
We struggled to find the reason for this. One possible explanation could have been due to clipping with the microphone. Because we got a relatively inexpensive microphone, we originally thought it would be best to speak with our mouths close to the microphone. After doing some research, it seemed like feeding loud audio to the microphone introduced clipping of the sound waveforms, which was making our model not work. After we moved further away from the microphone while speaking, our model worked more consistently, but still not perfectly.
To test this, we wired up a headphone jack with a voltage divider to feed the system the same audio files used to train the ML model on the Edge Impulse website. We found that when using the headphone jack, we had near perfect accuracy—meaning that the microphone was likely the cause of our issues.
RESULTS
Our tests involved speaking the name of a color, and seeing if the model would detect it, and displaying the classification percentages to the serial monitor. There was no hard collection of data to support the accuracy of our results. That being said, from our testing, the project had decent accuracy.
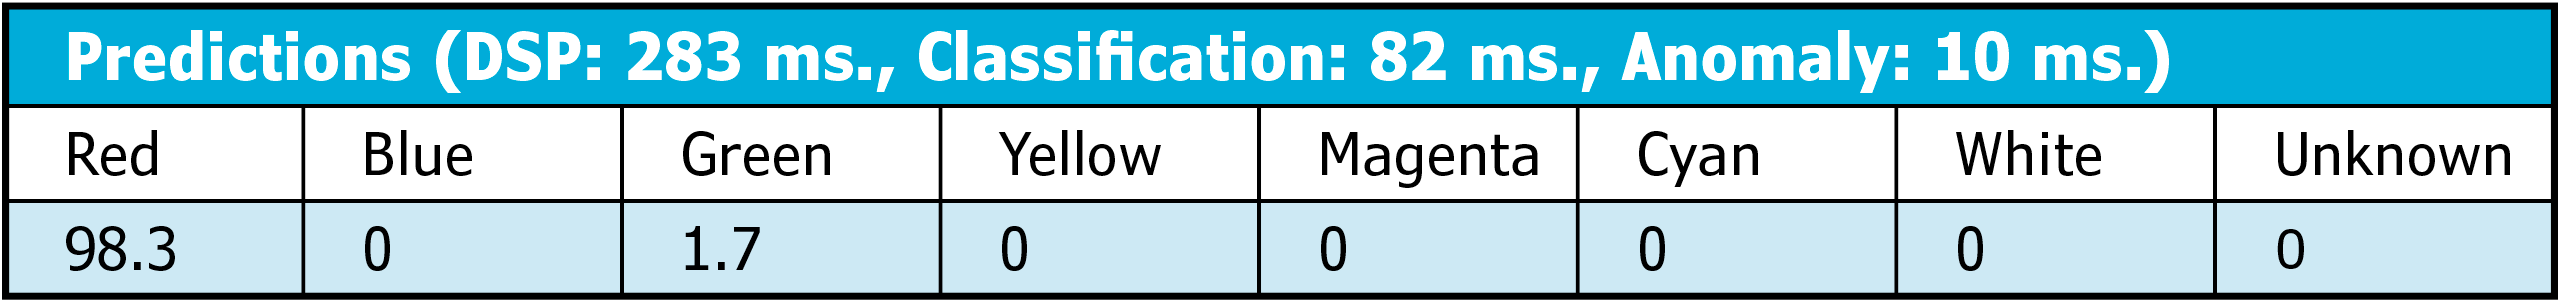
When detecting a color with perfect audio data, the model would classify it with a higher than 90% percentage, indicating that the model was functioning. For example, Table 1 shows a run where we fed it the audio data for “red.” From this data, you can see that the model detected red with 98.3% confidence and green with only 1.70% confidence.
Results of a run in which the model was fed perfect audio data.
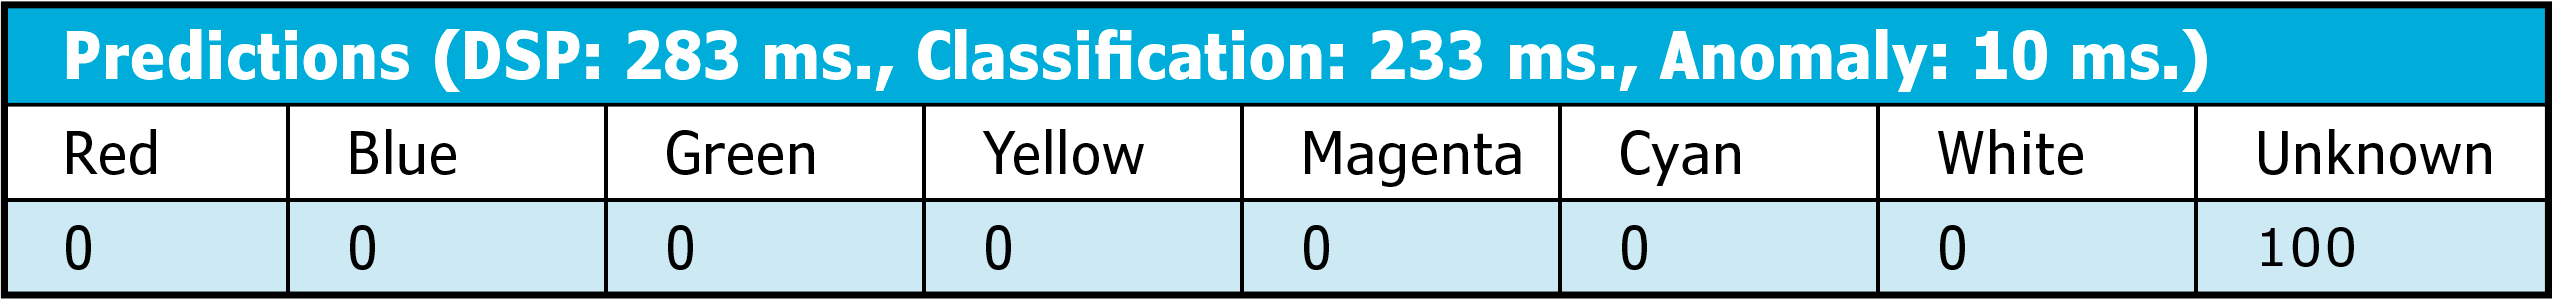
That being said, when feeding the model with imperfect audio data (for example, from the microphone) the results, shown in Table 2, often were unlike the result above. A result like this shows that the model was unable to classify the data. The last category displayed here is the “unknown” category, which means that model was unable to classify our audio against the model correctly. This happened randomly on the press of the button, with some words triggering this effect more than others.
Results of a run in which the model was fed imperfect audio data.
Usability was hit or miss with this project. Because the machine learning model was trained with our voices, it worked best with voices similar to ours. A higher-pitched voice might throw off the model or cause it to not work as well. Other individuals tried our project, and were able to get it to classify, thus indicating that voices that were not used to train the model can still be detected by our design.
CONCLUSION
Our main goal here was to run audio classification through an ML model, which we achieved. A video demonstration of the project is available on YouTube [5]. The final implementation worked well, but not perfectly, due to a few factors.
First, the machine-learning model we used was only trained with our voices and isn’t trained to the level of commercial-grade machine-learning models. Because of this, we had some inaccuracies with classifying the colors people were speaking. For certain colors, we would get almost perfect detection each time, due to the nature of the color. For example, magenta worked almost 100% of the time because the word “magenta” is distinct from other color names that people could say. In contrast, a color such as red, for example, is very similar in waveform to other one-syllable words, which makes it much harder to detect. A better trained model would help solve this inaccuracy. We had a hard time classifying some of the colors with complete accuracy. With more time, we could have trained the model with a wider range of audio samples to increase its accuracy.
Second, as discussed in the section on Design Problems, the audio data we received from the microphone was often clipped, due to problems caused by loudness.. Speaking too close to the microphone would cause clipping, and the project would fail to classify the results. When sending audio data recorded on our phones through the microphone jack we received almost perfect results. This suggests that with a better microphone with a pop filter, our project would work much better. An improvement would be to get a better microphone to feed data into the project.
Making and training the model, as well as integrating it with the Pi, was complex in nature. There was a lot of difficulty even getting the code to compile with the library provided by Edge Impulse. Feeding the audio signal to the model was also challenging, and required complex knowledge of both the Edge Impulse library and the ADC of the RP 2040. The hardware complexity came from wiring up the headphone jack and the microphone.
Intellectual Property Considerations: A lot of the inspiration for this project and some of the code we used for this project came from the book, TinyML Cookbook: Combine artificial intelligence and ultra-low-power embedded devices to make the world smarter by Gian Marco Iodice [2]. We specifically looked at Chapter 4 to learn about how ML works and how it can be implemented into a low-powered embedded device such as the Raspberry Pi Pico.
We also would not have been able to do this project without the use of Edge Impulse, a free development platform for machine learning. Our model was trained entirely with this platform, and the code to run the classification locally was packaged and created from their tool.
 RESOURCES
Edge Impulse | edgeimpulse.com
Raspberry Pi | www.raspberrypi.com
— ADVERTISMENT—
—Advertise Here—
REFERENCES
[1] Edge Impulse Documentation https://docs.edgeimpulse.com/docs/
[2] Gian Marco Iodice. TinyML Cookbook: Combine Artificial Intelligence and Ultra-Low-Power Embedded Devices to Make the World Smarter. https://www.perlego.com/book/3448797/tinyml-cookbook-pdf
[3] Complete project code on GitHub: https://github.com/TMSTweaks/Machine-Learning-On-Raspberry-Pi-Pico-with-Edge-Impulse/tree/main
[4] Edge Impulse allows the machine learning processing to be done on a local machine, instead of the Cloud https://docs.edgeimpulse.com/docs/run-inference/cpp-library/running-your-impulse-locally
[5] Demonstration video of our machine learning project: Machine Learning Voice Controller on RP2040 https://www.youtube.com/
PUBLISHED IN CIRCUIT CELLAR MAGAZINE • FEBRUARY 2024 #403 – Get a PDF of the issue
Sponsor this Article
Taylor Stephens is currently pursuing his master's degree in Systems Engineering at Cornell University. A recent 2023 graduate in Electrical and Computer Engineering, Taylor has distinguished himself through his academic rigor and a deep-seated passion for computer technology. Upon completing his master’s degree, he plans to work for Northrop Grumman as a Systems Engineer in their Mission Systems sector.
Zachary Hatzis graduated from Cornell University in May 2023 with a degree in Electrical and Computer Engineering. Currently he is a Software Development Engineer at Amazon in Seattle, Washington, working with Machine Learning to develop intelligent transcription tools for doctor/patient interactions.
Adam Fofana is from Philadelphia, PA. After graduating from Cornell University with a B.S. in Electrical and Computer Engineering, he went on to work at Vertiv in Delaware, Ohio as a firmware engineer. His work is focused on the company's data-server monitoring products. He currently lives in Columbus and hopes to venture into the tech startup space in the future.


