


Traditional microcontrollers can only run one instruction at a time. In the first of two articles, Wolfgang explains the basics of slicing time and programs into small pieces to make one instruction stream seem like two (or more).
What Could You Do with Multiple Simultaneous Programs?
Multitasking is running multiple programs simultaneously on a single processor. Because there is only one processor, they cannot be run simultaneously in the proper meaning of the term. Instead, they must be run piecemeal or in slices. Multitasking is a basic tenet of how processors are operated. The most common way to implement it is to rely on an appropriate operating system. Here, however, I will concentrate on basic principles characterized by control loops, interrupt service routines (ISRs), and switching from task to task.
WhY multitask?
As early as the beginnings of computer development, the idea arose of executing a second program while the currently running program is stuck in a waiting state. The most prominent causes of waiting states were the activities of input and output devices. Think, for example, of printing a text row, setting a magnetic tape in motion, or moving the read/write heads of a disk to the desired track.
The next step was to make the processor available to multiple users, each running their own programs. In the age of the personal computers, the main objective here is to enable the user to work with many applications concurrently.
— ADVERTISMENT—
—Advertise Here—
Another line of thought, beginning with employing computers in industrial process control, led to today’s embedded systems, in which a programmable processor serves as a substitute for application-specific functional units. It’s this kind of application that is the sole topic of our article.
Furthermore, we will restrict ourselves to small microcontroller applications and projects. Think, for example, of a microcontroller as the heart of a flatiron control unit, vacuum cleaner control unit, refrigerator control unit, and the like.
A general-purpose computer, whether a mainframe, a PC, or a mobile phone, is expected to run multiple applications of arbitrary size and functional complexity. Thus, the operating system must provide complete process environments, allowing each application to run as if the whole computer were solely at its disposal.
In contrast, microcontroller applications are constrained to a predetermined set of functions. We know how much memory, which peripheral units, and so on each function demands. With this knowledge, we can allocate the memory capacity from the beginning—the heater control needs X bytes, the speed control Y bytes, polling the keypad needs Z bytes, and so on. This way, we allocate specific runtime environments to each function or program to be executed simultaneously.
I call this application-specific runtime environment a partition. A process (such as, for example, in Windows) is a runtime environment that allows an arbitrary application to be executed; a partition is a dedicated runtime environment tailored to a specific function.
— ADVERTISMENT—
—Advertise Here—
Different operating systems
General-purpose operating systems are notoriously complex. Process swapping is slow. This is not caused by inept programmers, but by the sheer amount of work the system must do. Think of the windows on the screen, the frame buffers, the virtual memory, the file system, and so on. Everything must be taken into account.
So it’s no wonder that Windows, for example, takes milliseconds switching between processes, despite today’s processor speeds. In contrast, real-time operating systems (RTOSes) are optimized for fast task switching, low interrupt latencies, and other performance-oriented metrics.
At the high end are systems similar in size and complexity to the “big” general-purpose operating systems. Some are variants of Windows, Linux, and the like, while some are real-time companions to supplement these systems. Still others are full-fledged operating systems optimized for real-time applications. At the low end, some RTOSes are merely real-time kernels supporting task switching, basic communications, and file handling support.
Which to choose depends on your requirements and constraints, relating to functionality, performance, cost, and budget. Say your budget allows for X hours of development work. Could you do all the programming yourselves?
It comes down to the ubiquitous decision between make or buy. An obvious rule of thumb is to shop for an adequate RTOS, if complex standards of networking, file handling, graphics, and so on are to be supported. For small-scale projects, the decision is sometimes not so easy. No approach is free of effort, cost, and opportunities to make annoying mistakes. Only the kind of obstacles and impediments makes the difference, as seen in Table 1.
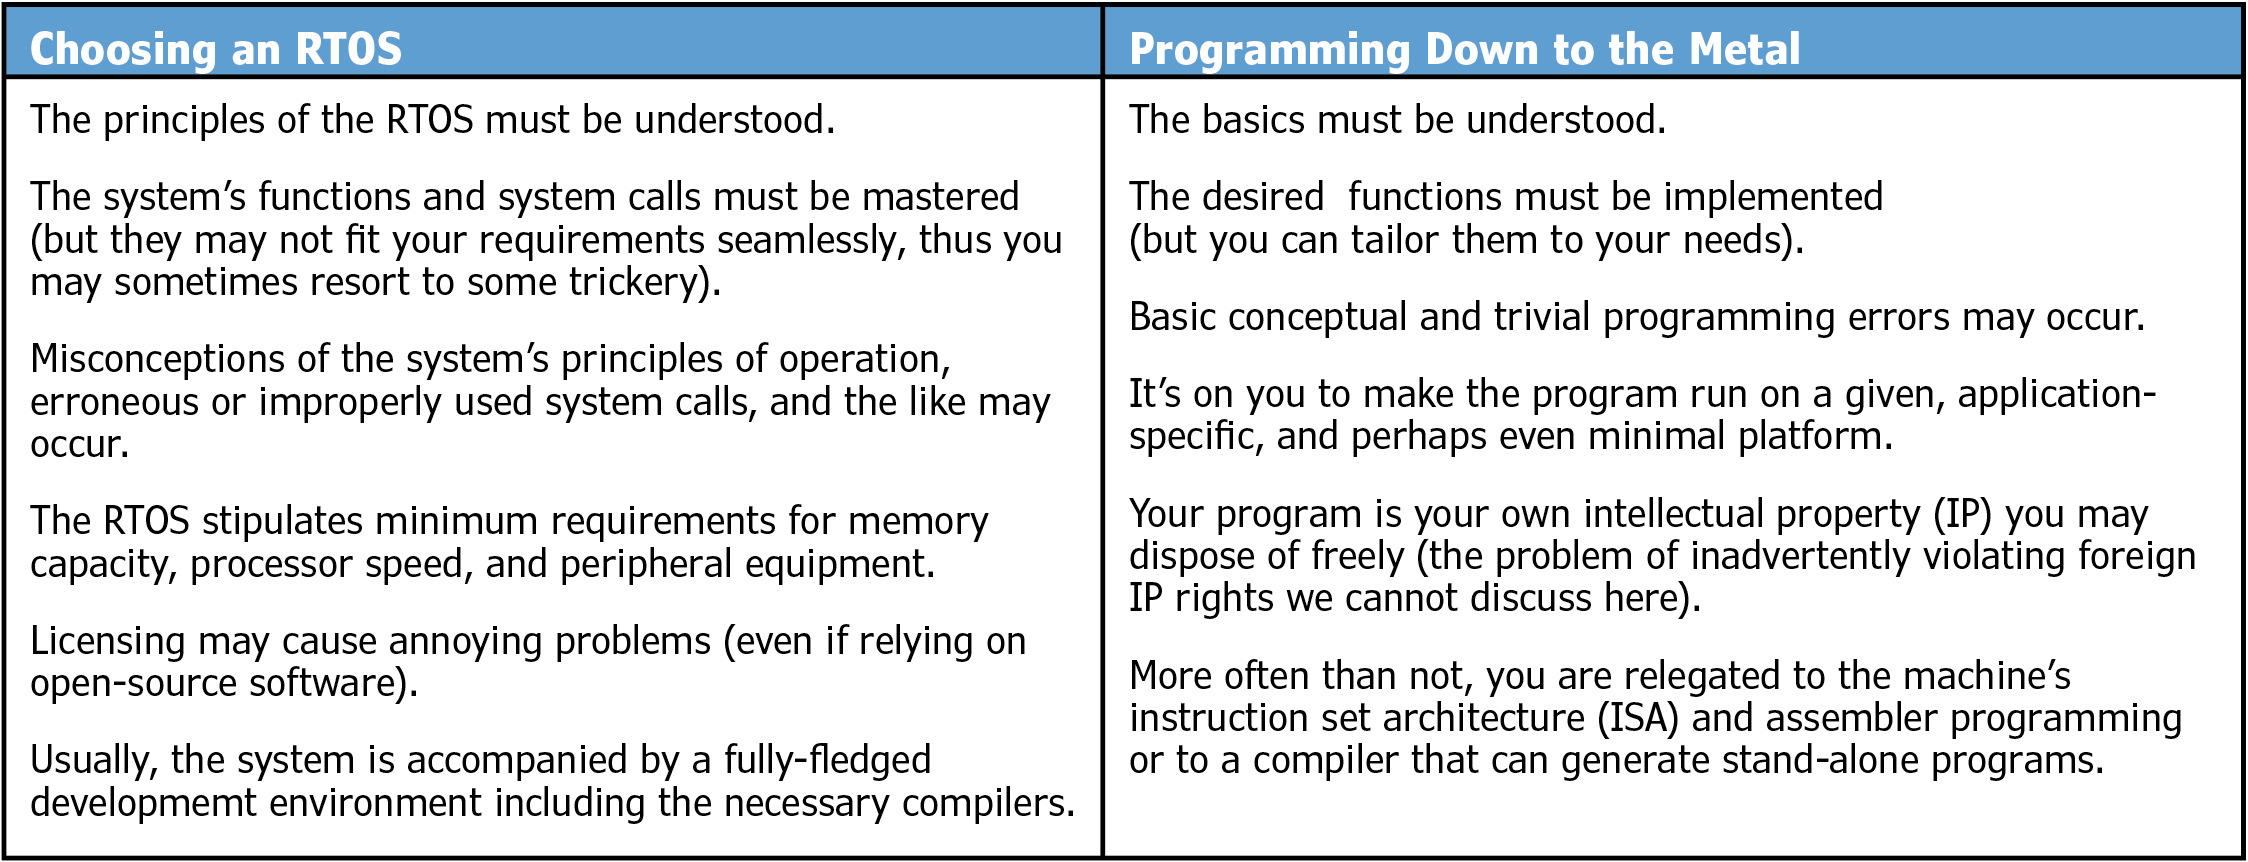
To implement multitasking in small-scale embedded systems, there are two principal approaches. The choice is yours.
A basic Start
While real-time operating systems (RTOSes) are plentiful ([1] to [4] introduce only a few examples), it doesn’t hurt to become acquainted with the fundamental principles. A venerable tenet of pedagogy is to let the student begin with doing basic tasks manually or the pedestrian way, so to speak. It could be likened to cutting a thread or milling a cogwheel on machine tools without CNC.
Many microcontroller applications do not need a fully fledged RTOS. Occasionally, implementing basic multitasking principles by programming down to the metal offers compelling advantages, especially for projects where costs need to be kept to the utmost minimum. In these cases, the overhead of sophisticated operating systems does not occur. We can get by with the least expensive microcontroller and must not bother about licensing conditions or license fees.
Multitasking in embedded systems
In a typical embedded system, the single processor serves as a substitute for the multiple functional units that would be otherwise implemented in hardware. The programs replace PCBs and integrated circuits.
Figure 1 shows a block diagram comprising functional units typical of embedded systems. In the distant past, the designers would have developed dedicated circuits, electromechanical, or even pure mechanical devices.

This block diagram depicts a generic embedded system comprising typical functional units.
Nowadays, you implement the functions by programming and executing programs on a single general-purpose processor.
The software takes over the tasks of the functional units. The hardware comprises only the sensors, interface adapters, power stages, buffers, converters, and so on, as well as the operating and display components that make up the human-machine interface (HMI).
So we can save on hardware, reduce costs, and provide additional functions nobody dreamed of in the old days, such as touchscreen operation, Internet access and never-ending live updates.
However, there is still only one machine available; only one program can run at a time. Therefore, the program components that implement the functions must be, so to speak, chained together, as shown in Figure 2. In electronic data processing (EDP) applications, one can first collect the workers’ performance data, then calculate the wages, deduct taxes, initiate the payments, and so on. This is not possible here. All functions must be available simultaneously within a timeframe determined by application requirements.

The software takes over the tasks of the functional units. Only sensors, level-converting stages, power stages, buffers, converters, and the like remain in the hardware, as well as the operating and display components of the human-machine interface (HMI).
Loops and interrupts
Microcontrollers or microprocessors, regardless of their gigahertz (GHz) and gigabytes (Gbytes), are still EDP machines executing one instruction after another. Once powered up and initialized, they execute an endless loop of instructions.
The succession of instructions can be modified only by conditional branching or by triggering interrupts. Consequently, a particular program can be invoked only by querying the corresponding request and branching, or via an interrupt (Figure 3). Thus, the endless control loop is the fundamental pattern of program flow. It asks what to do and starts the programs that carry out the requested activities.

Basically, programs run, following the initialization (a), in endless loops (b). A control loop (c) queries requests and calls programs to process them. Interrupts (d) enforce an excursion to another program, the interrupt handler. It could be considered a hardware-initiated subroutine call. Interrupt handling ends by returning to the interrupted program. Interrupting is by hardware, returning by instructions.
types of multitasking
Multitasking is called cooperative when switching from program to program is done by calling appropriate functions. In cooperative multitasking, the programmer must take care of proper runtime allocation.
Multitasking is called preemptive when switching from program to program is enforced by timer interrupts. In this case, the programmer need not take care of runtime allocation. Each application program can be written as if it owns the machine. We must only consider that it will run slower because it shares the processor with other programs.
The timeframe
Timing requirements arise from the application environment and the interfaces and devices to be supported. Think, for example, of sensors, analog-to-digital converters (ADCs), triacs to be ignited, keyboards to be scanned, displays to be refreshed, and so on. How long might it take to respond to requests (in other words, which latencies are permitted)? Does it matter if it takes a few milliseconds more or less?
Sometimes latencies of microseconds or less are required; sometimes seconds are irrelevant. We refer to such general requirements for real-time behavior as the timeframe requirements. To keep things clear in the following examples, we assume typical timeframes in the range of milliseconds.
Latency and response time
Latency and response time are typical parameters that characterize the speed at which a request is answered, as shown in Figure 4. Latency is the interval between the occurrence of a request and the first instruction to process it. Response time is the interval between the occurrence of a request and the first response occurring outside the processor (for example, the first output).

Here, typical timing parameters are illustrated. An interrupt has been triggered. (1) hints at the first instruction of the interrupt handler, (2) at the first instruction causing an effect outside the processor core (for example, think of an output instruction).
As a rule of thumb, latency depends on the system; response time depends on the application program. The latencies result from how fast the processor is, how the control loops and ISRs are organized, and so on. The response time depends on what the application program must do (for example, whether it has to multiply matrices or turn on a LED). Thus, the latencies are the decisive parameters.
The latency of programmed queries
The program must, so to speak, meet the request. To query a request, the corresponding instructions must be executed. Those instructions, however, are embedded in a control loop. The loop’s runtime can vary considerably because it depends on which functions are executed in each pass and how long they are delayed by waiting states.
In Figure 5a, the request X becomes active after the control loop has started. However, it will be queried at the end of the control loop. This results in a correspondingly long latency. If the request becomes active shortly after being queried, the response time is approximately equal to the runtime of the subsequent pass of the control loop. This is the worst case, as illustrated in Figure 5b.

Latencies. When the request is queried in a loop, the program can catch it only then if the querying instructions are executed (a). The worst case (b) occurs if the request becomes active right after those instructions. (c) illustrates the latency if the request is signalized by triggering an interrupt.
Interrupt latency
An interrupt request can be processed at any time, independent of which part of the control loop is currently executed (Figure 5c). The interrupt latency consists of three time periods. The first is caused by the processor’s interrupt mechanism. This is a datasheet parameter. The largest part, however, is made up of the two other periods: the time to save the current processor state and the intervals during which the interrupts are disabled.
Lightweight Interrupts
An interrupt is considered lightweight if its ISR needs only a few processor resources. Thus, only a small part of the processor state needs to be saved, and the latency will be short. A typical lightweight ISR uses only a few registers, accesses only its own dedicated memory areas, does not interact with the rest of the system, and cannot be interrupted. This contrasts with interrupts that initiate switching between threads or even processes.
This lightweight interrupt handler queries signals, fetches data from outside the program, outputs data, energizes acknowledgment signals, and so on. It performs input and output operations and tells the operating system that an event has occurred. For this, in addition to the instruction address, only the contents of a few processor registers need to be saved.
In many applications, these lightweight interrupts have a decisive influence on response times and data rates. Therefore, some architectures support such interrupts, above all, with multiple register files. In a historical example, the venerable Z80 microprocessor features two register files, swappable by exchange instructions. More advanced architectures have multiple register files, each assigned to a specific interrupt.
To interrupt a running program, register contents must be saved, beginning with the instruction counter. Typically, the instruction counter is saved and (later) restored automatically (similarly to calling a subroutine and returning from it). The other registers have to be swapped by appropriate instructions. Those housekeeping functions eat up many clock cycles. Therefore, querying requests in short loops may show less latency than signalizing them by triggering interrupts.
Sometimes, interrupts are not allowed
If processing the interrupt would delay execution of the interrupted program intolerably, interrupts may not be allowed at all. Figure 6 shows a straightforward example. The program generates two pulses. The pulse widths and offsets are determined by the instructions and the programmed delays (shown in Figure 6a). If an interrupt occurs in between, the pulse widths become unpredictable (shown in Figure 6b).

Generating pulses by programming (a) requires only a few instructions or subroutines. Interrupts, however, may change the timing unpredictably (b). Hence, they should be temporarily disabled (c).
When programming in assembler, the obvious remedy is to begin the instruction sequence with an interrupt disable instruction (DI) and end it with an interrupt enable instruction (EI), as shown in Figure 6c. Making the program temporarily uninterruptible, however, will increase the interrupt latency.
This explains why OS developers are concerned with keeping the uninterruptible sections of their programs as short as possible. Some RTOS suppliers highlight a very low interrupt disable time as a unique selling point. When writing application programs in a higher-level language, you are on your own to identify sections that must not be interrupted.
You hear talk of atomic, interrupt-safe, or thread-safe programs. To tell your compiler to make a section of your program behave accordingly, appropriate language or compiler statements are to be used. Regrettably, those means are not always documented clearly (as discussed, for example, in [5]). So, you may have to search around (in the documentation of the language, industry standards, user groups, optimization manuals, and so on). As a stopgap measure, you could resort to assembler programming and insert DI and EI instructions as necessary.
Choose wisely
If the timeframe requirements can be met consistently, a straightforward control loop is sufficient. If not, you can supplement the loop with interrupts. Sometimes the programs must behave like finite state machines (FSMs). If runtime allocation by cooperative multitasking becomes too complex, use multiple virtual machines, each running its own control loop. For runtime allocation, implement a straightforward round-robin time-slicing based on timer interrupts.
The endless loop is, so to speak, the natural way of querying requests, one after another. This serial processing avoids many conflicts of interrupt-driven operation. It might even be advantageous to organize your application solely as programmed loops. To guarantee the stipulated latencies and other real-time requirements, you merely choose a sufficiently fast processor.
One approach to interrupt handling could be to restrict it to lightweight interrupts that signal events or messages for the main control loop to process. Another could be to initiate time-critical programs by triggering interrupts and leave only such operations to the main control loop where a few milliseconds do not matter. In ancient times, this was called foreground-background processing: with time-critical programs running in the foreground and the rest in the background.
The Main Control Loop
The main control loop cyclically queries inputs and requests, executes the appropriate programs, and outputs the results. How many times the loop must be passed per second depends on the application and the functions to be supported. Elementary HMI devices (think of buttons, LCD displays, and the like) typically require 20 to 50 loops per second. Driving multiplexed LED arrays requires between 100 and 200 loops.
Control tasks related to the mains AC voltage should be completed within half a mains cycle. In the 60Hz power grid, this equates to approximately 8ms. In such a time interval, a typical small microcontroller executes several thousand instructions.
The loop shown in Figure 2 illustrates how multi-purpose functional units can be replaced by software emulating one functional unit after another. However, programming in this way will likely lead to intermittent malfunctions.
This is because the program components may operate on different input values and produce independent outputs. To fundamentally avoid such sources of error, the program must behave somewhat like a FSM, as known from automata theory.
Essentially, it must be a sampling system: first, all inputs are sampled, then all decisions and calculations are performed, and finally, all results are output. The fact that input, processing, and output each require several program steps is irrelevant. The only important thing is that all the programs work with one set of data, first collected, then processed, and subsequently output, not with a mixture of old (previously acquired) and freshly generated data.
Figure 7a shows an appropriately structured control loop. It first reads the input data, then executes the control algorithms, and finally activates the outputs. In the vast majority of cases, the program must interact with both the inputs and outputs of the application environment (sensors, relays, power stages, and the like) and with HMI components, such as buttons, LEDs, and graphic displays. Thus, there are two kinds of program modules: one serves the application environment, the other the HMI. This is illustrated in Figure 7b.

The endless main control loop is the typical fundamental control program structure in embedded systems.
Sometimes, the application environment’s interfaces and devices require responses in microseconds. The HMI routines, however, allow for a much more generous timeframe (think of, for example, the scanning and debouncing of a keypad). Here, some milliseconds, more or less, will not matter.
Figure 8 illustrates an alternative solution. The requirements of the application environment determine how long a cycle of the main control loop may last. To guarantee this, the actual control program (which can be formulated using ladder diagrams, instruction lists, function blocks, or programming languages) is not organized as an endless loop, but is called cyclically via a timer interrupt, for example, every 20ms. The machine then behaves like a finite state machine.

The main loop supports only the human-machine interface (HMI). All time-critical control operations are cyclically invoked by a timer interrupt.
First, communication with the various devices is established (for example, via CAN bus or Ethernet). Then the inputs are read, the control algorithms are executed, and finally the outputs are written. Between these cycles, the processor queries the keys and switches, and refreshes the displays.
HMI support can often be programmed without regard to tough timing requirements. For example, when a key is actuated, the program may wait in a loop until it is released (provided it has nothing more important to do), because every 20ms the timer interrupts will cause the time-critical control program to run again.
Here, we are concerned with how to provide for multitasking operation below a fully-fledged RTOS. Beginners may ask how one comes up with such ideas. In short, they originate chiefly from experience and by tinkering. Thus, they are scarcely a topic in academic textbooks.
Over the decades, numerous developers have figured them out when money and deadlines were tight. Imagine, for example, you have to develop a vacuum cleaner, and the microcontroller may cost, under no circumstances, more than, say, 56 cents. Today, appropriate app notes (such as [6] and [7]) are only rarely available. As a remedy, I propose introductory literature about RTOSes and app notes on problems closely related to multitasking, such as motor control, serial interfaces, or touch sensing.
RTOSes are based on the very same principles. Only the level of complexity is higher. Because of this, thinking like an RTOS developer (as stated in [2]) is undoubtedly valuable advice, whether you are an RTOS user or an ardent programmer trying to devise solutions of your own.
Tough, time-critical tasks
Frequently, applications require programs that must, at any cost, run cyclically. Think, for example, of refreshing a multiplexed LED display or a conventional LCD panel (without internal buffering), or of igniting a triac in each half wave of the mains voltage. I call such programs hard endless loops, regardless of whether they are true loops or are invoked cyclically by interrupts.
How can hard endless loops coexist with programs subject to lenient timeframe requirements? It can be done by cooperation or preemption, as Figure 9 and Figure 10 illustrate. There, the HMI support consists of querying three keys. When a key has been depressed, the program branches to a routine that implements the appropriate function. Then it waits for the key to be released. This program runs as the main control loop.

A hard endless loop is executed as a subroutine called cyclically, that is, by cooperative multitasking.

A hard endless loop is executed by invoking it cyclically via a timer interrupt, that is, by preemptive multitasking. It is the principle already depicted in Figure 8. In the main control loop, functions with more lenient timing requirements are executed, including the routines that support the human-machine interface (HMI). The time-critical functions are implemented as interrupt service routines (ISRs).
According to Figure 9, the program representing the hard endless loop is written as a subroutine. To run it cyclically, it is to be called in all wait loops.
In this way, the problem of runtime allocation can be solved entirely by software. However, how often the hard endless loop is run depends on the operating state of the main control loop and thus on the user behavior.
Sometimes this is a problem (for example, when controlling power stages), sometimes it’s not (for example, when cyclically refreshing LCD panels).
A deterministic timeframe results when the hard endless loop is started via interrupts triggered by a timer (preemptive multitasking). As shown in Figure 10, the hard endless loop is written as an interrupt handler. Since it starts automatically, the main control loop doesn’t need to worry about it. Even cycling in a loop for many seconds, while waiting for a key to be released, does not impede the proper execution of the hard endless loop.
The timing budget
How often the hard endless loop must be executed per second depends on the application’s and the HMI’s timing requirements. Let’s assume, for example, that 50 passes per second are stipulated. A timer interrupt is to be triggered every 20ms. Consequently, the hard endless loop should be passed in less than 20ms. What remains is available for serving the HMIs and other clerical tasks (Figure 11). The question is whether it is sufficient.

A timing budget example.
The obvious approach is to shop for a sufficiently powerful processor. As a rule of thumb, given today’s processor speeds (hundreds of MHz), 32-bit platforms allow for completely programming even exceptionally ambitious projects in high-level languages without trickery and arduous optimization.
time-slicing
Instead of intermixing programs invoked by the main control loop and ISRs, we provide for running more than one main control loop simultaneously by time-division multiplexing, or cyclic task switching based on timer interrupts. Each task has its own processor state, comprising the contents of the processor’s registers, including the instruction counter and the flags. In principle, it’s some kind of virtual machine. We may write the programs as if they have sole control over the processor’s resources.
Partitions
Every task needs an area in memory to store its processor state and the local data, including stack and heap (the latter, if used in the application program). Such an area we call a partition. It is somewhat similar to a process, such as, for example, in Windows, but considerably smaller and far less complex.
Task switching means saving the processor state of the active task into its partition and fetching the processor state of the next task out of its partition (Figure 12).

Task switching means saving and restoring processor states. Each task has an area in memory where the processor state is retained as long as the task does not run.
How the partitions are structured and by which instructions the processor state is saved and restored, depends on the processor’s architecture. For example, we could set aside an appropriately sized area in each partition (as depicted in Figure 13) and use store instructions to save the processor state and load instructions to restore it. Each of these instructions, however, contains a memory address.

To support multitasking, the memory is allocated as shown here. Besides the common memory that contains programs, global variables, and so on, each partition is allocated its own area. We may imagine a partition as a means to run a task similar to a process as a means to execute a thread. In our humble projects, however, there is nothing analogous to the process swapping of the “big” OSes.
An alternative would be to save the processor state onto the stack, provided the processor architecture supports stacks in memory. Stack-related instructions are short because the stack pointer (SP) takes care of memory addressing. Besides, saving and restoring the instruction address requires no effort because it is intrinsic to stack operation. Therefore, the following example will be based on this principle.
an AVR example
Our example is based on the AVR microcontroller architecture, showing that the principles can be implemented with low effort on small microcontrollers and applied to projects typical of this class of machines. It could, however, be passed on to any other architectures featuring general-purpose register files and supporting stacks in memory.
Next, we will only illustrate the memory layout and the principles of operation. An Internet addendum provides more details, including source code examples.
Figure 14 shows how the memory is allocated. Our example is based on four partitions. Each has a Partition Control Area (PCA), comprising the partition’s stack as well as local variables and data. A Global Control Area (GCA) contains pointers pointing to each PCA and identifying the currently active partition.

In our example, the memory is partitioned and allocated as shown here.
Furthermore, in the GCA, the stack pointers (SPs) of the inactive partitions are saved. Remember that memory allocation and partitioning are to be done application-specifically and manually. The good news, however, is short latencies, predictable real-time behavior, and low resource requirements.
When a timer interrupt occurs, the current processor state is saved onto the stack of the current partition, as shown in Figure 15. Then switching to the next partition will commence.

The processor state has been pushed onto the stack. This example alludes to typical RISC architectures (including AVR but omitting the subtleties of this architecture).
The program flow is illustrated in Figure 16. Figure 16a depicts the initialization and Figure 16b shows the task switching from partition to partition. First, the registers are pushed onto the stack, then the stack pointer is saved to the GCA, and then the next partition is selected. The Current Partition Pointer (CPP) is advanced cyclically so that it addresses now the PCA pointer and (by an appropriate displacement) the stack pointer of the next partition. Thus, this saved stack pointer can be moved to the processor. Finally, the register contents are popped from the stack of the next partition. Returning from the interrupt, the next partition resumes operation.

Principal initialization and task switching.
Time slices
The shorter the time slice, the shorter the latency, but the longer the overhead. Table 2 shows values that apply to an AVR microcontroller operated at 4MHz. This comparatively humble frequency has been chosen with lower supply voltage and power consumption in mind.
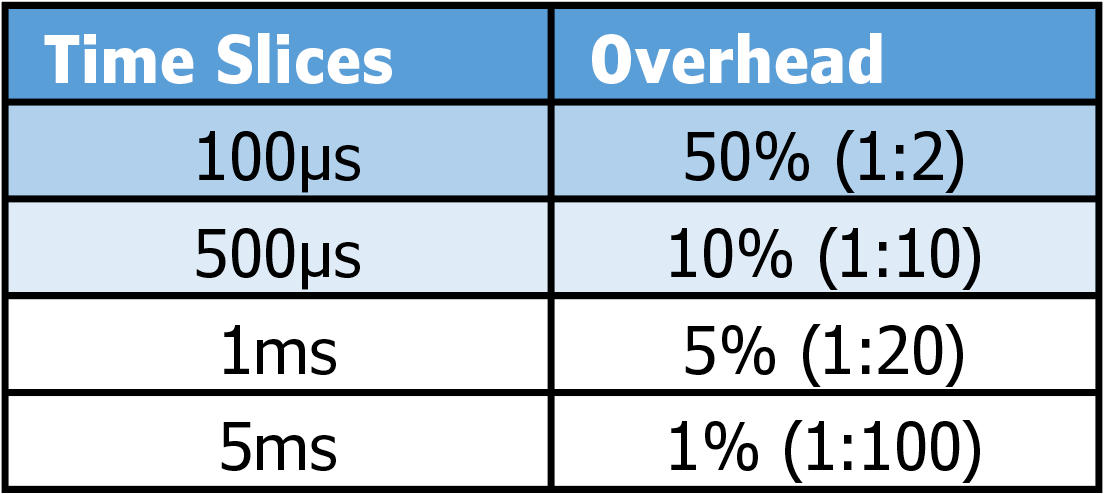
The task switching performance data shown here are related to an AVR microcontroller operated at 4MHz. Applying the maximum clock frequency todays AVRs specified for, task switching times could be at least divided by four, resulting in about 12.5µs.
Task switching takes about 50µs. From five milliseconds upward, the overhead can mostly be neglected (less than 1%). Such time slices are sufficient for many applications (think of a mains half-wave every 8ms, scanning a keyboard every 20ms, and so on).
No Free Lunch
In most embedded systems, microcontrollers act as substitutes for application-specific functional units. Developers strive to handle most tasks by software and reduce application-specific hardware to the minimum. To design such programs, one must know the principles of multitasking. Here, we have introduced control loops, lightweight ISRs, and round-robin task switching.
Applying such principles requires programming to the metal. This leads to the question of resorting to a well-established RTOS to avoid wasting time on minor quirks and re-inventing the wheel.
You must find the best answer for yourself. None of the alternative approaches will be a free lunch. Working hours are always required; mistakes may always occur. As a rule of thumb, you may prefer the approach described here if it is for fun, self-study, or small, cost-sensitive problems.
On the other hand, if networking is to be supported, file systems and the like, there will probably be no other option than shopping for a suitable RTOS and providing an adequate hardware platform. However, even if you have chosen this approach, it is advantageous to know something about the basics.
RTOS developers start from the same fundamentals. Once we know something about those fundamentals, it is less difficult to understand the principles of operation on which the RTOS is based and how to use it optimally.
Think low-level, write high-level (as the title of [8]) states) is a tried and tested adage. Furthermore, it would be easier to delve deeper into open-source RTOS software and modify it according to your needs.
An Internet addendum provides more details and source code examples. The next article will cover multitasking principles centered around the event concept.
REFERENCES
[1] Mørch-Thoresen, Eira: Getting Started with FreeRTOS on megaAVR® 0-series. Application Note AN3007. Microchip Technology Inc. 2019.
https://ww1.microchip.com/downloads/aemDocuments/documents/MCU08/ApplicationNotes/ApplicationNotes/FreeRTOS-on-megaAVR0series-DS00003007B.pdf
[2] Atmel AVR10008: ASF Specific FreeRTOS Functionality for Peripheral Control. Atmel Corporation 2012.
https://ww1.microchip.com/downloads/aemDocuments/documents/OTH/ApplicationNotes/ApplicationNotes/doc42049.pdf
[3] Valenti, Chris; Kalman, Andrew E.: Multi-Tasking on the PIC16F877 with the Salvo™ RTOS. Microchip Technology Inc. 2001.
https://ww1.microchip.com/downloads/aemDocuments/documents/MCU08/ApplicationNotes/ApplicationNotes/00777b.pdf
[4] Labrosse, Jean J. : Code and data size for an RTOS-based design. IAR 2025.
https://www.iar.com/knowledge/learn/code-and-data-size-for-an-rtos-based-design/
[5] Keeping safe at C: How to neutralize some of the inherent dangers of the language. IAR 2024. https://www.iar.com/knowledge/learn/keeping-safe-at-c/
[6] Berringer, Ken: Vacuum Cleaner Reference Platform. Application Note AN1843. Freescale Semiconductor, Inc. 2004.
https://www.nxp.com/docs/en/application-note/AN1843.pdf
[7] Mackay, William: Embedding Microcontrollers in Domestic Refrigeration Appliances. Application Note AN1853. Freescale Semiconductor, Inc. 2004. https://www.nxp.com/docs/en/application-note/AN1853.pdf
[8] Hyde, Randall: Writing Great Code, Voume 2: Thinking Low-Level, Writing High-Level. No Starch Press, San Francisco 2006.
RESOURCES
The author‘s project homepages: https://www.realcomputerprojects.dev
https://www.controllersandpcs.de/projects.htm
Some links to microcontroller manufacturers and RTOS providers:
https://www.iar.com/
https://www.microchip.com/
https://www.nxp.com/
https://www.weston-embedded.com/
Some links to more specific RTOS knowledge:
https://www.iar.com/knowledge
https://www.nxp.com/design/design-center/software/embedded-software/mqx-software-solutions/mqx-real-time-operating-system-rtos:MQXRTOS
https://www.nxp.com/design/design-center/software/embedded-software/azure-rtos-for-nxp-microcontrollers:AZURE-RTOS
https://www.nxp.com/design/design-center/development-boards-and-designs/MCU-RTOS-MATTER-DEV-PLATFORM
https://www.weston-embedded.com/cesium-kernels
https://www.weston-embedded.com/micrium-books
PUBLISHED IN CIRCUIT CELLAR MAGAZINE • JUNE 2026 #431 – Get a PDF of the issue
Sponsor this Article
Wolfgang Matthes has developed peripheral subsystems for mainframe computers and conducted research related to special-purpose and universal computer architectures for more than 20 years. He has also taught Microcontroller Design, Computer Architecture and Electronics (both digital and analog) at the University of Applied Sciences in Dortmund, Germany, since 1992. Wolfgang’s research interests include advanced computer architecture and embedded systems design. He has filed over 50 patent applications and written seven books. (www.realcomputerprojects.dev and
www.controllersandpcs.de/projects).


